Introduction
Modern customers pick up mobile gadgets and look for shopping portals or social networks to load without delay. Sudden network failures, hardware defects, or messy updates can stall vital online platforms in seconds. Site Reliability Engineering blends regular programming work with continuous operations duties to protect critical applications. Clever engineers craft defensive software barriers so platform issues never bother everyday shoppers or gamers. SRESchool.com serves as a global knowledge center where technologists and corporate teams study modern reliability concepts. Members gain the real ability to secure complex computer systems through interactive assignments, sandbox labs, and seasoned guidance.
What Is SRESchool.com?
Consider an aircraft crew that installs self-checking instruments so jet engines adjust themselves smoothly during rough storms. Site Reliability Engineering works on that same basic principle by using smart code to safeguard server clusters. Specialists track daily operational health, measure tiny delays, and build scripts that resolve repeating glitches without human intervention. Whenever unexpected software faults strike, teams avoid pointing fingers and instead mend the structural faults in the system. This steady cycle of measuring, automating, and learning preserves platform balance as consumer numbers multiply rapidly.
Why Does SRESchool.com Matter?
Large enterprises run complex networks of cloud nodes, transaction records, web servers, and high-speed data cables. A single dropped server thread or frozen database call can lock out thousands of shoppers in an instant. Annoyed visitors quickly exit the failing application, post bad reviews, and spend their cash on a rival service instead. SRE teams track sensitive telemetry numbers to spot subtle memory leaks before customers run into broken checkout carts. Building reliability into standard product cycles protects company profits, preserves brand trust, and removes stressful late-night server emergencies.
What Does an SRESchool.com Team Do?
A platform engineer inspects incoming requests, processor loads, and database speeds on big display boards. Automated paging systems wake up designated engineers the moment a bad error rate crosses an established limit. The technician reviews prebuilt operational steps, removes bad code updates, and brings back full service for waiting users. Next, the team crafts background automation so computers resolve that exact problem alone during future shifts. They also review past traffic numbers to buy surplus computing instances before heavy holiday shopping events arrive. Finally, the group gathers for a calm postmortem session to design solid platform fixes that prevent repeat outages.
Key SRE Terms Made Easy
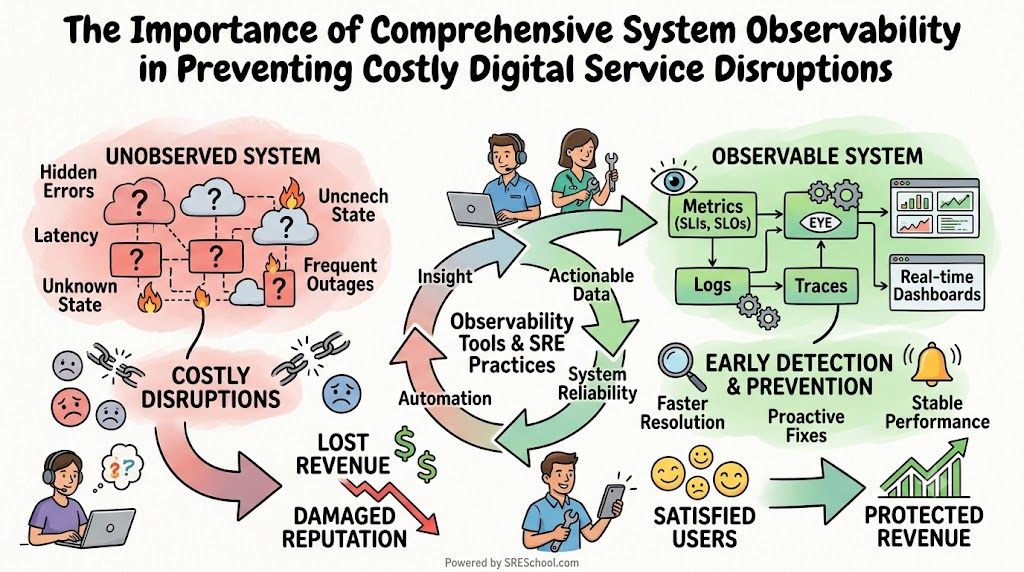
Engineers rely on short technical expressions to evaluate system stamina and make informed delivery decisions. A Service Level Indicator measures real operational performance, such as network delay or successful page requests. A Service Level Objective represents the formal target percentage that the engineering team agrees to hit consistently. An Error Budget marks the exact slice of downtime a team can safely use before halting risky software releases. Operational toil represents boring, repetitive computer tasks that a basic shell script could finish instead. Observability allows engineers to diagnose mysterious software failures by collecting system metrics, error logs, and request traces.
| SRE Term | Simple Meaning | Example |
| SLI | A direct measure of real system performance or speed. | Tracking the percentage of checkout requests that finish in under two seconds. |
| SLO | The official uptime target promised to end users. | Keeping website availability above ninety-nine point nine percent each quarter. |
| Error Budget | The allowed margin for unexpected platform downtime. | Having twenty-one minutes of permitted system disruption across an entire month. |
| Toil | Repetitive manual maintenance tasks that lack enduring value. | Copying database backup files between different test servers by hand every morning. |
| Observability | The ability to inspect internal software states using outside signals. | Reading distributed request traces to pinpoint the exact microservice causing slow lookups. |
| On-Call | An active shift where an engineer responds to alerts. | Carrying an emergency laptop over the weekend to triage critical system panics. |
| Incident | An unexpected system breakdown that degrades normal business functions. | A database failure that prevents online customers from viewing their shopping baskets. |
What Is SRE Training?
Curious technologists join SRE Training programs to master core infrastructure design and production operations skills. Beginners explore foundational system health metrics, craft bash automations, and configure realistic Service Level Objectives. They study techniques for balancing error budgets, reading system logs, and leading calm blameless postmortem discussions. Cloud labs allow students to troubleshoot broken container clusters inside safe practice environments without harming live users. SRESchool.com delivers hands-on educational pathways that help professionals wipe away tedious manual maintenance through intelligent automation. These real-world exercises give technicians the practical confidence needed to tame unexpected enterprise infrastructure crises.
What Is SRE Certification?
A recognized SRE Certification signals to technology recruiters that a candidate understands modern cloud reliability standards. A Certified Site Reliability Engineer proves ability in tracking system performance, mitigating outages, and designing automated self-healing scripts. Formal training programs offer clear learning milestones that cover observability frameworks, distributed networks, and incident triage methods. Yet passing a test is merely the foundation of an engineer’s broader professional career path. True mastery requires coupling exam knowledge with actual troubleshooting on messy, unstable production servers. Great engineers showcase their skill through successful production fixes rather than test scores alone.
What Is a Site Reliability Engineering Course?
An effective Site Reliability Engineering Course walks students along a logical, step-by-step path toward operational mastery. Beginners start with basic Linux terminal commands before configuring telemetry agents and drafting Service Level Objectives. Afterward, students simulate live outages, build self-healing scripts, and control containerized cloud systems at scale. Students explore an exhaustive SRE Tutorial collection to review difficult architectural ideas through straightforward analogies. This practical approach assists junior coders, seasoned developers, and system administrators as they elevate their production skills. Tackling realistic incident simulations prepares technicians to handle real enterprise computing pressures with steady competence.
SRE Tools Made Simple
Engineers configure specialized SRE Tools to track system vitals, expose bugs, and resolve application failures quickly. Programs such as Prometheus scrape performance metrics like processor usage, available disk storage, and network packet rates. Dashboards built on Grafana display these data points as intuitive, real-time charts that highlight strange performance anomalies. Distributed tracing frameworks like OpenTelemetry follow single user clicks across complex networks of internal services. Automation software deploys updated code containers, replaces failing nodes, and scales server clusters automatically. Combining these powerful tools allows engineers to resolve hidden bottlenecks before external users experience any disruption.
| Learning Area | What Learners Can Practice |
| Metrics Collection | Configuring Prometheus to monitor memory consumption across cloud instances. |
| Visual Dashboards | Designing clear Grafana panels to visualize current transaction speeds. |
| Distributed Tracing | Instrumenting web code with OpenTelemetry to track slow database queries. |
| Automated Recovery | Crafting Python scripts that restart crashed background workers automatically. |
| Infrastructure as Code | Deploying identical, throwaway testing environments using simple software blueprints. |
Real-Life Scenarios and Experiences
- An unexpected viral video directs massive crowds of new shoppers to a boutique clothing site. Auto-scaling rules detect the rapid CPU spike and spin up fifteen fresh cloud instances within minutes. The storefront continues processing orders cleanly without freezing customer screens or dropping connection requests.
- A developer deploys a flawed database migration that slows down mobile banking account lookups. Latency metrics climb past the agreed Service Level Objective threshold and trigger an immediate high-priority alarm. The responder instantly reverts the deployment, restores sub-second lookup speeds, and preserves the team’s error budget.
- A technician wastes two hours every afternoon manually restarting memory-heavy analytics workers on several servers. The worker writes a simple daemon script that checks process memory and restarts bloated tasks automatically. This quick automation eliminates boring operational toil and returns ten hours of productive time every week.
- A severe lightning strike takes down an entire regional data center without any advance warning. Smart routing layers recognize the dead region and divert incoming traffic to an alternate operational site. Users experience no service interruption while platform engineers assess the storm damage safely from afar.
What Is SRE Consulting?
Enterprises often engage SRE Consulting advisors to evaluate their computing setups and identify fragile system dependencies. External specialists audit alert configurations, inspect continuous integration pipelines, and help department heads define sensible reliability targets. They teach internal teams how to replace manual administrative chores with modern cloud automation workflows. Advisors also coach staff to run productive, blame-free postmortem meetings that identify true operational flaws. Partnering with a reliability consultant enables companies to scale digital infrastructure quickly while dodging catastrophic architecture errors.
What Is SRE as a Service?
Fast-growing organizations without internal operations units contract SRE as a Service to gain round-the-clock infrastructure protection. Outside reliability specialists handle production monitoring, configure incident alerting policies, and step in during critical outages. These engineers optimize telemetry displays, run disaster recovery exercises, and guarantee cloud capacity expands smoothly with customer traffic. However, business owners must outline exact operational requirements before signing agreements with an external provider. Clear boundaries ensure outside specialists protect system uptime without hindering internal developers from launching new features.
What Is Corporate SRE Training?
Forward-thinking technology departments choose Corporate SRE Training to unite developers, quality analysts, and operations personnel under shared practices. When every engineer speaks the same operational language, teams build durable, crash-resistant software right from the beginning. Instructors adapt curriculum labs to mirror the enterprise’s specific cloud architectures, tool pipelines, and internal security guidelines. Teams run simulated incident drills together so everyone stays calm and coordinated during real production disruptions. Sponsoring collective technical education tears down operational barriers, shrinks mean time to recovery, and guarantees stable business software.
Common Mistakes to Avoid When Choosing Reliability Programs
- Enrolling in theoretical courses that lean on text slides while skipping hands-on terminal command sessions.
- Prioritizing multiple-choice test preparation over actual hands-on programming and infrastructure automation practice.
- Studying legacy, physical server setups rather than modern containerized workflows and distributed cloud ecosystems.
- Registering for generic training that never demonstrates how error budgets influence daily code deployment decisions.
- Trusting instructors who lack proven experience managing real, high-traffic consumer systems through severe outages.
- Selecting educational programs that completely ignore incident management drills, alert routing, and postmortem documentation.
- Believing a wall certificate guarantees employment without assembling a portfolio of functioning automation projects.
- Committing to rigid training curricula that do not let engineering teams experiment with their own operational tools.
How SRESchool.com Can Help
SRESchool.com functions as an international training and consulting resource for engineers pursuing modern reliability excellence. Students can join an intensive Site Reliability Engineering Course to build relevant, hands-on production skills. The educational center provides structured study paths for technicians seeking to earn their Certified Site Reliability Engineer credential. Organizations can schedule customized Corporate SRE Training to upskill their development and infrastructure teams together. Businesses can also retain seasoned advisors through professional consulting and managed reliability offerings to reinforce complex cloud environments. By offering rich documentation and practical guides, the platform equips every technologist to design dependable, highly scalable platforms.
Frequently Asked Questions
1. What is Site Reliability Engineering?
Software engineers implement programmatic scripts to resolve classic hardware deployment, scaling, and computer networking headaches. This modern operational strategy replaces manual button clicks with automated logic and sets clear availability targets for cloud applications. Engineers spend their working hours preventing software outages rather than running around fixing broken servers by hand. The strategy balances the need for rapid product delivery with customer demands for uninterrupted uptime.
2. Do I need coding skills to learn SRE?
Basic programming literacy gives candidates an enormous advantage because reliability engineers write automation logic and inspect application code daily. Most professionals lean on straightforward languages like Python, Go, or Bash to create monitoring tools and administrative scripts. You do not need to create complex consumer web applications, but you must write code that parses system logs and restarts servers. Accessible starter courses quickly teach you the primary scripting syntax needed for typical cloud infrastructure duties.
3. What is the difference between DevOps and SRE?
DevOps represents an organizational culture that promotes close communication and shared responsibility between developers and operations staff. Site Reliability Engineering delivers the practical handbook, daily rituals, and technical measurements needed to realize those cultural ideals. DevOps directs teams to break down silos, while SRE defines metrics like SLOs to track success. Both concepts work together to help software organizations ship reliable updates quickly and safely.
4. What is an error budget?
Error budgets represent the exact amount of acceptable downtime or system imperfection a digital product can sustain each month. The value is simply one hundred percent minus your service’s official Service Level Objective target. An objective of ninety-nine percent leaves a one percent error budget for the current calendar period. Teams burn this allowance to release experimental features, launch big updates, or absorb unexpected hardware failures.
5. What does operational toil mean?
Repetitive administrative duties that provide zero enduring value to the underlying technology stack represent operational toil. These low-level chores multiply in lockstep with business growth, address no root system defects, and deplete valuable engineering hours. Typical examples include manually updating configuration files on individual servers or periodically purging temporary log caches. SRE engineers eliminate these boring chores through automated scripts, freeing up time to build better platform features.
6. How long does it take to learn SRE?
Dedicated beginners usually gain a dependable grasp of fundamental reliability concepts within three to six months of study. Prior experience with Linux server administration, computer networking, or general software programming speeds up your progress considerably. Mastering distributed platform designs, enterprise incident triage, and deep system telemetry requires several years of hands-on production experience. Consistent daily practice with virtual cloud labs helps learners master these complex operational skills much faster.
7. Why are postmortems important in SRE?
Teams write a formal postmortem report after resolving a critical system outage or unexpected software crash. The document details the timeline of events, explains the technical failure, and outlines steps to prevent future recurrences. SRE practitioners maintain a blameless culture that studies fragile system designs rather than targeting individual human errors. This supportive learning mindset guarantees that discovered operational defects lead to permanent technological defenses across the enterprise.
8. What are the best tools to learn first?
Aspiring engineers should begin by mastering fundamental Linux terminal operations, bash scripting, and Git version control systems. Next, pick up Prometheus to collect system health metrics and Grafana to build responsive visual monitoring dashboards. Learning container engines like Docker and orchestration systems like Kubernetes is also vital for modern cloud engineering roles. Practicing with these standard technologies provides the core skills required to operate enterprise software reliably.
9. Can small startups use SRE practices?
Early founders can apply fundamental reliability patterns straight away without hiring a dedicated operations specialist for their staff. Early-stage startups should establish basic uptime objectives, automate their deployment pipelines, and configure central error alerts immediately. Building strong operational habits early protects developers from accumulating crippling technical debt as the user base expands. Thoughtful reliability planning ensures that your digital platform scales gracefully alongside incoming customer traffic.
10. How does SRE improve system security?
Consistent reliability habits bolster application defenses by maintaining uniform, patched, and constantly checked cloud instances through automated workflows. Automated deployment pipelines allow engineers to push emergency security patches across hundreds of servers without costly manual errors. Comprehensive telemetry sensors flag unexpected network connections or unusual CPU spikes before malicious attackers do widespread damage. A dependable, well-architected infrastructure network presents fewer loose components and fragile cracks for hackers to exploit.
11. What is an on-call rotation?
Engineering teams run on-call rotations so someone is always awake and ready to handle critical production alerts. When automated monitoring systems detect an active outage at midnight, the paging tool alerts the scheduled technician. The engineer logs in, follows established recovery playbooks, fixes the broken component, and informs the business. Fair rotation schedules protect user service uptime while preventing individual engineers from experiencing excessive stress and burnout.
12. Is an SRE certificate enough to get hired?
Earning a formal certification displays your personal dedication, but employers also evaluate your actual hands-on troubleshooting capabilities. You should build personal homelab projects, automate cloud resources with code, and document your experiments in public repositories. Demonstrating how you diagnose broken services and design resilient architectures gives recruiters confidence in your technical skills. Blending formal study certificates with a strong portfolio of practical automation code creates an attractive engineering resume.
Conclusion
Every successful digital venture depends on Site Reliability Engineering to maintain stable, responsive cloud services and consumer databases. The framework unites fast-paced software updates with unwavering operational stability through targeted telemetry, smart automations, and constructive incident reviews. Aspiring technicians build these competitive abilities by completing guided lessons, building personal test environments, and achieving industry qualifications. Simultaneously, established enterprises rely on team training and specialist advisors to reinforce critical production frameworks. SRESchool.com supplies the comprehensive tutorials, sandbox practice environments, and professional instruction necessary to run dependable platforms. Embracing these engineering habits today prepares your software systems to scale smoothly through future traffic surges.
